Private Cloud Workers
This page is no longer maintained. These docs have moved to Self-Hosted Pool.
Run Cloud Agents in your own infrastructure.
Private Cloud Workers are in closed beta. Contact Cursor for access.
Overview
Private cloud workers let you run Cloud Agents within your own environments. This is useful for two reasons:
- Your codebase stays in your environment. Only the chunks of files the model reads leave your network.
- You can use existing machines you already have set up in the cloud. This reduces setup work (build caches, private dependencies), and lets you use controls from your own environment.
Architecture
In all Cloud Agents, the Agent Loop (maintains state, calls inference) is separated from the process that executes tool calls (terminal commands, file edits). With Private Cloud Workers, the tool-execution process runs in your environment.
Stays in your network
Full repo on disk. Secrets and credentials. Build caches and artifacts. Private registries and internal APIs.
Crosses to Cursor
Tool results (stdout, diffs, file reads). Worker metadata for routing. Selected prompt context for inference. Real-time progress streamed to the Cursor UI.
Running agent worker start opens a long-lived outbound connection to Cursor's cloud; no inbound ports or ingress rules are required. The agent loop sends tool calls over this connection, and your worker executes them against local tools (terminal, filesystem, browser). Each cloud agent instance gets its own dedicated worker.
Example
A step-by-step walkthrough showing what runs where (e.g. "Fix the flaky payment test"). The agent loop handles planning and inference; tool calls run on your worker.
- 1
User sends the prompt from cursor.com/agents.
- 2
The agent loop calls Inference (LLM) with the prompt + relevant file context. Inference (LLM) responds: "read
tests/payment.test.ts, then run the test suite." - 3
The agent loop sends a "read file" tool call to your worker through Cursor's network. Your worker reads
tests/payment.test.tsfrom disk and sends it back.The file never leaves your network. Only the chunk Inference (LLM) needs is sent for inference. A regular Cloud Agent would need a full clone on Cursor's VMs. - 4
Inference (LLM) generates a fix and calls "apply edit". The worker patches the file on your disk.
- 5
Inference (LLM) calls "run terminal command":
npm test --filter payment. Your worker runs this inside your network. It hits your private npm registry, your internal test database, your build cache.A regular Cloud Agent runs in Cursor's cloud. If your private registry, internal DB, or build cache are only reachable inside your network, use a private worker to access them directly. - 6
Tests pass. Inference (LLM) decides to commit, push, and create a PR (generates the tool calls), but the actual git commands execute on the worker. The diff, commit output, and PR URL stream back to the Cursor UI in real-time.
Git credentials and push access stay on your machine. No need to share tokens with Cursor's infrastructure.
Test locally (quick start, 5 min)
Prerequisites
- Cursor team plan — Private Workers are a team feature.
- A git repo — The worker directory must be a git repo with a
remote.origin.urlconfigured. - Feature flag access — Contact Cursor to enable Private Workers for your team.
- Outbound HTTPS — Allow outbound HTTPS (port 443) to:
- Cursor API for auth (default endpoint is
https://api2.cursor.shandhttps://api2direct.cursor.sh) - Cursor downloads for the CLI installer (
https://downloads.cursor.com) - If you use a proxy, set
HTTPS_PROXYorhttps_proxy. The bridge client will use it for outbound connections.
- Cursor API for auth (default endpoint is
Run this on any machine with the repo cloned; your laptop is fine.
Enable Private Workers in the dashboard
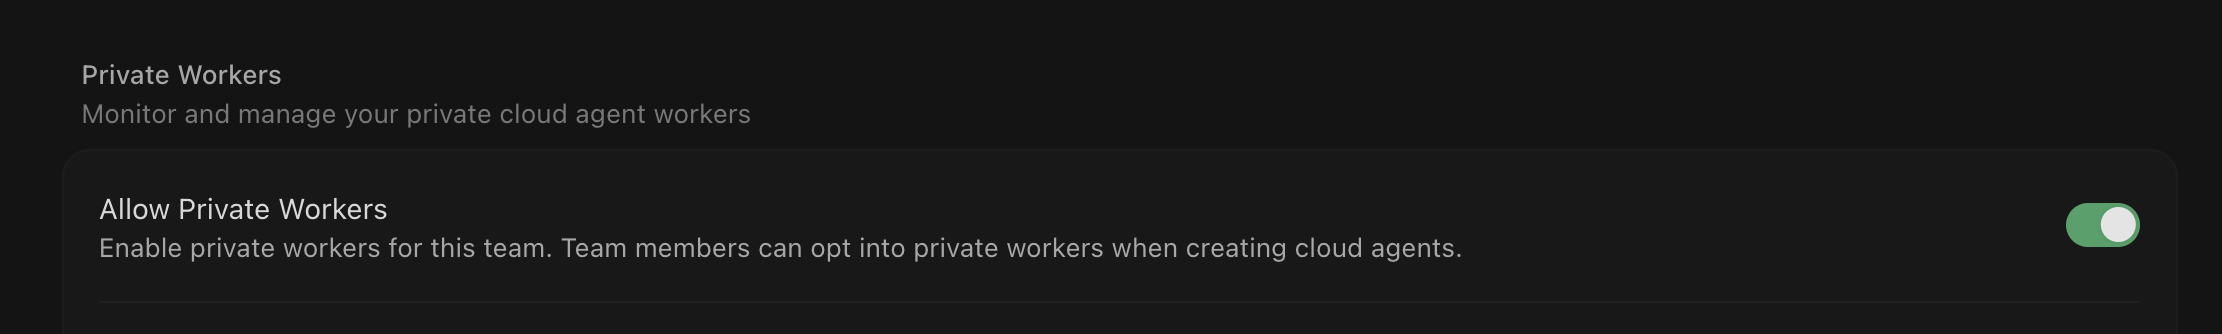
Before you install the CLI or start a worker, a team admin must turn on Private Workers for the organization on the Cloud Agents dashboard.
Install the CLI
Install the agent CLI using the default installer or a custom URL (includes lab channel to get fast releases):
curl -fsSL "https://www.cursor.com/install?channel=lab" | bashEnsure ~/.local/bin is on your PATH so the agent command is available. See the CLI docs for more info.
Authenticate
Private workers support two auth methods. Pool workers require a service account API key. CLI login only works for non-pool testing.
1. Existing CLI login (for testing)
agent loginOpens a browser window. After you authenticate, the CLI stores a token locally. Best for one-off testing on your laptop.
If CURSOR_API_KEY is set, it takes precedence over CLI login. Unset it before relying on CLI login:
unset CURSOR_API_KEY2. Service account API key (required for pool workers)
Create a service account API key via the service accounts docs and pass it via flag or environment variable. Pool workers reject other API key types.
agent worker start --api-key "your-service-account-api-key" --worker-dir /path/to/repoIn Kubernetes, store the key in a Secret and reference it as an env var (see Deploying).
The same service account API key works for the fleet management API. Pass it via Basic auth (-u "$CURSOR_API_KEY:") or Bearer token.
Start a worker
Navigate to your repo and start the worker:
cd /path/to/your/repoagent worker startOr pass the path explicitly:
agent worker start --worker-dir /path/to/your/repoTo register the worker for pool assignment, use --pool with a service account API key:
agent worker start --api-key "your-service-account-api-key" --worker-dir /path/to/your/repo --poolYou should see the worker appear in the Private Cloud Workers section of the Cloud Agents dashboard.
Monitor workers in the dashboard
After your workers connect, open the Private Workers Dashboard to monitor and manage your fleet. The dashboard shows how many workers are connected, which workers are in use, which workers are idle and ready for new agents, and which repo, workspace, labels, and active agent are attached to each worker.
Team admins can also use the Require Private Workers for All Cloud Agents setting in the dashboard to require team members to use private workers instead of Cursor's default cloud infrastructure.
Who can see idle team workers
- Admins can see idle team-scoped private workers and overall team capacity.
- Members do not see idle team-scoped workers in the dashboard by default.
- If a team-scoped worker is already assigned to one of a member's active cloud agent sessions, that member can still see the assigned worker for that session.
Send a task to your worker
- Go to cursor.com/agents.
- Select the repo that matches your worker's directory from the dropdown.
- Check "Use private worker" above the input box.
- Send a task, e.g., "Fix the flaky payment test in tests/payment.test.ts"
The worker directory doesn't have to be a git repo. When it has a remote.origin.url, the worker registers that repository for routing. Repeat --worker-dir to serve several checkouts. See Register multiple repo roots.
Deploying
After testing locally, the next step is running workers on machines that are provisioned and managed automatically.
The designs below are self-managed patterns for the current beta. A managed orchestration layer (Helm chart + Kubernetes operator) is on the roadmap.
A production deployment has three parts: labels to describe workers, a scaling strategy to create workers when capacity runs low, and an idle release timeout to recycle machines after sessions end.
Labels
Workers can provide as many label keys as needed, and keys do not need to be unique. Labels can be passed as command-line arguments, or via a JSON or TOML file. The file path can be passed via command-line arguments or via CURSOR_WORKER_LABELS_FILE.
The repo label is reserved and must use the format owner/repo_name. Single-repo workers with a git origin URL in the workspace root automatically derive and register the repo label, so you don't need to set it manually.
Good for quick testing or when you only have a few labels:
agent worker start \ --label env=production \ --label size=large \ --worker-dir /path/to/repo--label and --labels-file are mutually exclusive. Use one or the other.
Idle release timeout
After a session ends, workers stay connected and wait for follow-up messages. The --idle-release-timeout flag controls how long (in seconds) a worker waits before exiting. The default is 3600 seconds. You can also set it via the CURSOR_WORKER_IDLE_RELEASE_TIMEOUT environment variable.
When the timeout fires, the CLI exits with code 0. If a follow-up message arrives before the timeout, the timer resets and the worker keeps running. If a follow-up arrives after the CLI has already exited, the agent claims a new eligible worker automatically.
The idle release timeout only starts counting after a session ends. While a session is active, the worker stays connected regardless of this value.
Shorter timeouts for production
For ephemeral infrastructure where you want machines recycled quickly, set a short timeout:
agent worker start \ --idle-release-timeout 600 \ --worker-dir /path/to/repoThis gives a 10-minute window for follow-ups before the worker exits and the machine can be recycled.
Long-lived workers
For persistent machines -- such as a personal dev server or a dedicated team box -- set a very large timeout to keep the worker alive indefinitely:
agent worker start \ --worker-dir /path/to/your/repo \ --idle-release-timeout 3153600031536000 seconds is roughly one year, effectively preventing the worker from exiting due to inactivity. This gives you a persistent, long-lived worker that is always ready for new tasks.
Scaling strategies
Example 1: Kubernetes Deployment with readiness probes
This pattern uses Kubernetes-native scaling. No external polling or custom autoscaler needed.
How it works:
- A Kubernetes Deployment runs pods whose startup command is
agent worker start. Each pod has the repo cloned and is labeled (e.g.,repo=org/repo_name,size=small). - A user starts a cloud agent, selecting labels that match.
- One pod is claimed. The management server on that pod (
/readyz) starts returning 503. Kubernetes has a readiness probe on this endpoint and creates a new pod to keep ready capacity stable. - After the session ends, the worker exits (controlled by
--idle-release-timeout), the pod terminates, and Kubernetes replaces it.
Health checks:
Enable the management server so Kubernetes knows when a worker is available vs. busy:
agent worker start \ --management-addr ":8080" \ --worker-dir /path/to/repo| Endpoint | Returns 200 when | Returns 503 when |
|---|---|---|
/healthz | Process is running (liveness) | Never (if the process is up, it's healthy) |
/readyz | Connected to Bridge and not claimed | Starting up, or currently running a session |
The /readyz endpoint is the key integration point. When a worker gets claimed, it flips to 503. Kubernetes removes it from the ready pool, and the Deployment spins up a replacement to maintain capacity.
Example 2: Kubernetes Jobs with API-driven scaling
This pattern uses the Cursor API to monitor capacity and a custom controller to create workers on demand.
How it works:
- A controller creates a Kubernetes Job per worker.
- The controller polls
/v0/private-workers/summaryperiodically to get counts of workers running and in use. When idle workers drop too low, it creates another worker Job. - Workers exit with code 0 after
--idle-release-timeout, which marks the Job as complete.
See the API reference for all available endpoints.
API reference
These endpoints let you monitor and manage your worker fleet programmatically. Pass a service account API key via Basic auth (-u "$CURSOR_API_KEY:") or Bearer token (Authorization: Bearer $CURSOR_API_KEY).
List workers
curl --request GET \ --url "https://api.cursor.com/v0/private-workers?status=idle&limit=50" \ -u "$CURSOR_API_KEY:"Query parameters:
| Parameter | Type | Default | Description |
|---|---|---|---|
status | all | in_use | idle | all | Filter by worker status |
limit | integer (1-100) | 50 | Results per page |
pageToken | string | Pagination cursor: the nextPageToken from the previous response |
Response:
{ "workers": [ { "workerId": "a8574fe8-248e-424a-a078-7584a2b93724", "repoOwner": "acme", "repoName": "payments-service", "workspaceRootPath": "/workspace", "connectedAtMs": 1737306880000, "userId": 321, "teamId": 44, "serviceAccountId": "sa_abc123", "isInUse": false, "name": "build-machine-1" } ], "nextPageToken": "NTA=", "totalCount": 53}Get worker summary
curl --request GET \ --url "https://api.cursor.com/v0/private-workers/summary" \ -u "$CURSOR_API_KEY:"Response:
{ "userSummary": { "totalConnected": 2, "inUse": 1, "teamWorkersInUseByUser": 0 }, "teamSummary": { "totalConnected": 8, "inUse": 7 }}Get worker by ID
curl --request GET \ --url "https://api.cursor.com/v0/private-workers/pw_123" \ -u "$CURSOR_API_KEY:"Response:
{ "worker": { "workerId": "a8574fe8-248e-424a-a078-7584a2b93724", "repoOwner": "acme", "repoName": "payments-service", "workspaceRootPath": "/workspace", "connectedAtMs": 1737306880000, "userId": 321, "teamId": 44, "serviceAccountId": "sa_abc123", "isInUse": true, "activeBcId": "bc-00000000-0000-0000-0000-000000000002", "name": "build-machine-1" }}Scaling guidance
Use the summary endpoint to monitor utilization and scale when capacity is tight:
const response = await fetch( "https://api.cursor.com/v0/private-workers/summary", { method: "GET", headers: { Authorization: `Basic ${Buffer.from( `${process.env.CURSOR_API_KEY}:` ).toString("base64")}`, }, });const summary = await response.json();const team = summary.teamSummary;if (team && team.totalConnected > 0) { const utilization = team.inUse / team.totalConnected; if (utilization >= 0.9) { // Scale up: provision additional private workers }}CLI reference
agent worker start [options]
| Flag | Description |
|---|---|
--worker-dir <path> | Working directory (default: current directory). Must be a git repo. |
--management-addr <addr> | Address for /healthz and /readyz (e.g., :8080, 0.0.0.0:8080). |
--label <key=value> | Add a label (repeatable). Mutually exclusive with --labels-file. |
--labels-file <path> | Path to JSON or TOML labels file. Mutually exclusive with --label. Env var: CURSOR_WORKER_LABELS_FILE. |
--idle-release-timeout <sec> | Seconds to stay connected after session ends. Default: no timeout (worker stays connected until stopped). Env var: CURSOR_WORKER_IDLE_RELEASE_TIMEOUT. |
--pool | Register for pool assignment. Each session claims one worker at a time. |
--single-use | Legacy alias for --pool. |
--api-key <key> | Service account API key. Required for pool workers. See Authenticate. Env var: CURSOR_API_KEY. |
-e, --endpoint <url> | API endpoint (default: https://api2.cursor.sh). |
agent worker --help # See all optionsagent login # Interactive browser-based authagent --version # Check CLI version